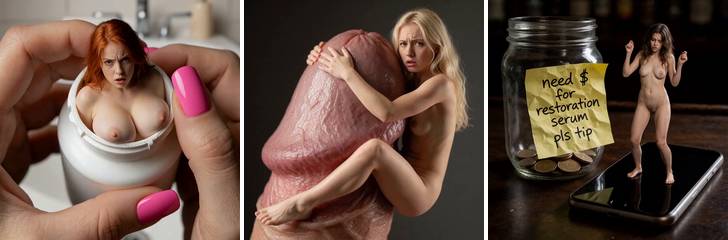
For the past few weeks I've been experimenting with local AI video generation. The results are pretty good. Still some limits, of course. Here are the details and a few of the clips I was able to generate. This was all done locally on my machine using publicly-available AI models.
I have been able to generate much more explicit scenes than I've shown here, but they're honestly not nearly as interesting.
PREVIEW
VIDEO LINKS (enable sound!)
https://www.redgifs.com/watch/loyalwrathfulocelot
https://www.redgifs.com/watch/splendidq ... hbutterfly
https://www.redgifs.com/watch/illunusedthrush
---------
Fair warning first
This is not a beginner setup, and you can't copy it in an afternoon. Everything runs locally on my own machine: no cloud services, no paid generation sites, no uploading anything anywhere. Getting it to this point took deep familiarity with how these models work and a software engineer's mindset:
- custom nodes and patched workflows;
- separate Python environments for tools that conflict with each other;
- Linux tools running alongside Windows;
- debugging GPU memory;
- building my own front end to tie it together.
The machine
- GPU: one RTX 5090 (32 GB). Everything shares it, so only one job runs at a time.
- CPU: Ryzen 9 9950X3D (16 cores).
- RAM: 128 GB. Big models spill into system RAM, and some steps need a lot of it.
- Storage: a 2 TB NVMe for the active models and outputs, plus a 4 TB SSD for rarely used models. The model collection gets big fast.
- OS: Windows 11, with a Linux environment (WSL) for tools that only behave on Linux. Some of them hold a GPU model in memory between jobs, so there's no reload wait.
- ComfyUI is the engine, running as two separate installs: one for image, video and most audio, and one for voice tools whose dependencies would break the main install. They share the model folders and outputs.
- Custom nodes fill the gaps: dialogue takes, per-speaker audio stems, lip-sync repair, sound generation and so on.
- Private-network access lets me check renders from my laptop or phone without exposing anything to the internet.
Each clip is 10–40 seconds: a woman shrunk to a few inches tall, stuck somewhere absurd (a bowl of ice cream, a bottle, a hoop earring, taped to a desk), talking with a friend who's mostly off screen. The friend is just a voice and a hand, finger or thumb. The comedy is deadpan, irritated banter against a ridiculous situation.
What works
1. Get the script right before generating anything.
The script establishes the characters, situation, dialogue and actions. Clear descriptions of who's speaking, what's happening and what should remain consistent help the models produce better results. I refine the dialogue and pacing before moving into generation, rather than trying to fix structural problems afterward.
2. The start image does half the work. Everything starts from a still made in Krea, with character LoRAs for any recurring characters. Macro or tilt-shift photography, the scale relationship spelled out, the props named. I reroll until the scale, the tape, the hands and the expression are right, and keep the keepers in sets per scene.
3. Dialogue is recorded separately from the picture.
- Each character has a fixed cast voice, chosen from a library of over a thousand I've procedurally generated.
- Every line is generated on its own, and I pick the best variant.
- A good take becomes the reference for the next line, so the voice stays consistent.
- Lines go onto a DAW for timing and pauses.
- Then the whole take is combined as a single audio file, so I can re-render the picture endlessly and the performance never changes.
- Only the on-screen character's voice drives her lips.
- A little room tone under the dialogue stops the picture jumping between lines.
- A separate lip-sync repair pass redoes just the stretch that's off.
- one track per speaker;
- an ambience bed;
- music when it fits;
- Foley (finger rubs, tape, mouth sounds) timed to the picture.
6. Treat every glitch as fixable. When something breaks the illusion, I find why and fix the cause. Most fixes became permanent steps.
What didn't work (so you don't have to try it)
- Letting the video model make the voices. Voices drifted, landed on the wrong character, and came with a noisy floor. Recording the dialogue separately fixed all three.
- Generating the whole conversation in one pass. Lines ended up on the wrong speaker. Prompt tricks didn't help either: panning, "the voices must sound different", rewording the voices. Per-line recording is the only reliable fix.
- Yelling and ALL CAPS in lines. They trigger jump cuts. Calmer delivery words don't.
- Timing words in prompts ("at 3 seconds she…"). Ignored. Screen time follows word count, so a long description of a one-second action gets four seconds. Keeping action beats short and similar in length works better.
- "While she's doing X" overlapping actions. They work about half the time at best.
- Speed hacks:
- drafting small and upscaling distorted faces;
- "refine" passes repainted the mouths and broke the sync;
- rendering at half the frame rate and interpolating was twice as fast but destroyed the lip sync;
- compiler-style optimisations wouldn't run with my quantized models at all;
- most fast-sampling add-ons looked the same or worse than what I already use.
- Tiny full-body framing. It looks amazing as a still, but below a certain face size the lips stop syncing. Worse, the video model "cheats" by cutting to a close-up of a different face.
- Over-describing the shot. When I wrote "her face is large, looking up at the camera", I got a giant's face looming in the background. Describing the lens position ("the lens just above her") and saying "the rest of the giant is off-camera" fixed it.
- Identity from reference pictures instead of LoRAs. Character LoRAs win easily; references alone drift or clone faces.
- Posing mannequins or re-posing photos for start images. More trouble than it was worth.
- Trusting automatic scores over my ears. An "expressiveness" metric picked the flattest reads. Listening is the only judge that works.
- Two people on screen at once. Lip sync wants one mouth. With two visible speakers, both mouths move, or the wrong one does, and the lip-repair pass can only fix one face per run. For now I keep the second person off screen (a voice and a hand), which happens to suit the format.
- The world drifting over a long clip. Longer scenes are rendered as chained shots, and things creep in at the joins: sizes shift, an extra hand appears, a nail colour changes. Tight wording in the context paragraph and rerolling seeds help, but nothing solves it.
- Short lines mouthed too long. A two-word line like "Okay. Cool." sometimes gets mouthed for an extra second. The section repair pass fixes it after the fact, but I'd rather it didn't happen.
- Scale versus lip sync. The more convincingly tiny she looks, the smaller her face is, and the worse the sync. Every shot is a compromise between the two.
- Whispers and laughs. Whispered lines barely move the lips, and laughs or giggles are hit and miss in the voice pass.
- Re-editing after the take. Combining or splitting lines after the take is frozen used to scramble the sync. That's patched now, but I re-check every re-edit.
One clip took about 180 renders before I was happy. Across all the scenes there are about 550 saved dialogue takes and nearly 2,000 individual line variants. All of it was rendered on one GPU at home. It's a lot of iterating, but because the layers are separate, fixing one doesn't break the others.
If you take one thing away
Don't ask one model to do everything. Separate the script, the image, the voices, the picture and the sound, lock each one in before moving on, and judge every layer with your own eyes and ears.
Where this is going
Right now these are just experiments. If enough people are interested, I’m thinking about starting a store (Clips4Sale or similar) with longer compilations and polished versions of the scenes. That would mean higher resolution, the full sound mix, and some exclusive scenes that won’t be posted for free. Nothing’s set up yet, so if that’s something you’d actually buy, say so in the replies. It’ll tell me whether it’s worth doing.
Happy to answer questions about the pipeline in the meantime, especially if anyone has cracked two people talking on screen.